Reviewed by Product Specialist at thinQit. Updated 16 October 2026.
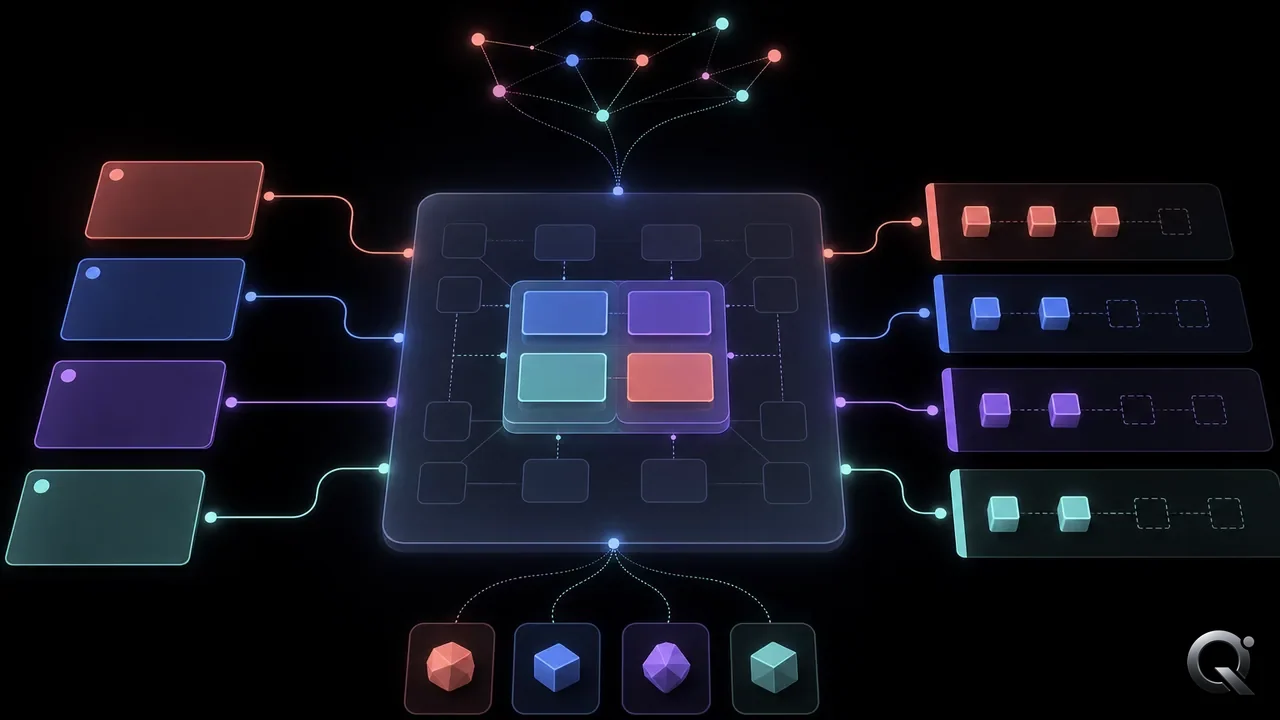
Shared project context gives every AI agent building the same app the same approved picture of the work: the user outcome, scope boundary, decisions, source material, dependencies, and acceptance evidence. It prevents one agent from designing against an old assumption while another writes code against a newer one, and it gives reviewers a single record to test before a change is accepted.
What shared project context contains
Shared project context is a working delivery record, not a long prompt copied into every task. It holds the information that must remain consistent across design, implementation, testing, content, and release work. The record is useful when each item is specific enough to guide a decision and narrow enough to be checked later.
For an app build, the minimum record usually states the problem being solved, the intended user, the workflow that must work, the constraints that cannot change, and the evidence required for approval. It also separates confirmed decisions from open questions. That distinction matters because an AI agent should not turn an unanswered question into an implementation choice.
A useful context item has an owner and a status. A product decision can be approved, pending review, superseded, or blocked. A source item can be current or replaced. An agent can then use the item that is valid now instead of treating every note in a workspace as equally authoritative.
Why AI agents need one source of truth
AI agents building one app need one source of truth because parallel work creates dependency risk. A UI agent can complete a screen that no longer matches the data model, while a developer agent can implement a workflow that a reviewer has already narrowed. Shared context makes the dependency explicit before that mismatch becomes rework.

A single record does not mean every agent receives every detail. Each agent needs the subset that governs its task, plus the links to upstream decisions and downstream acceptance checks. The shared layer preserves the relationship between those subsets. When a decision changes, the team can identify which tasks, prompts, tests, and review criteria must be revisited.
This is different from storing context in chat history. Chat history is chronological and often contains alternatives, partial conclusions, and informal language. A shared project context is curated: it records the active decision, the evidence for it, and the point at which it was approved.
How to set up an AI project canvas
An AI project canvas for website approvals provides a compact place to organise shared context before agents start independent work. Set it up as a controlled procedure, then update it whenever an approved decision changes.
- Define the outcome. State the user action or business result the app must support. Avoid a feature label alone, because a label does not define what success looks like.
- List the scope boundary. Record what the build includes and excludes. Include interfaces, integrations, data, and workflows only when they are approved for this release.
- Attach source material. Link the approved brief, designs, requirements, examples, and technical constraints. Mark a replacement when a source is no longer current.
- Record decisions as decisions. Write the chosen option, the reason it was chosen, its owner, and its status. Keep open questions separate so agents do not infer an answer.
- Map dependencies. Identify which task depends on which decision, component, data shape, or review. A dependency map tells an agent when it must stop and ask rather than continue.
- Define acceptance evidence. Specify the page state, test result or preview, with live as another option readback that proves the work meets the outcome. Evidence makes a handoff reviewable.
- Version changes. When a decision changes, keep the change record and mark affected work for review. Do not silently overwrite a decision that another agent may already have used.
How agents should consume the context
Each AI agent should begin with a task boundary, relevant context items, and a definition of done. The task boundary identifies the files or pages, with workflow as another option the agent may change. Relevant context explains the intent and constraints. The definition of done states the evidence the agent must return, such as a preview, a test result, or a live verification.

Agents should cite the decision identifiers or context links they used in their handoff. That practice gives a reviewer a fast way to compare the result with the approved requirement. It also exposes a gap early: if an agent cannot find an approved answer for a required choice, the correct outcome is a question or a blocked task, not an invented assumption.
Keep execution notes separate from the context itself. A build log can record commands, review comments, or temporary investigation. The shared record should retain the decisions and facts that later work must reuse. This separation keeps the context readable as the project grows.
What to update when a requirement changes
A requirement change is safe to handle when the shared context is updated before agents continue from the old version. First describe the changed outcome or constraint. Then identify the affected decisions, tasks, tests and content, plus evidence. Finally, invalidate or reopen work that depended on the earlier version.
The goal is not to freeze a project. It is to make change visible and traceable. The guide How Does AI Documentation Keep Decisions Current? explains how a decision record remains useful after a build begins. The practical rule is simple: a changed requirement must leave a visible trail from the new decision to the work that needs another review.
Common failure modes
The most common failure is treating a kickoff brief as permanent context. A brief starts the work, but it does not automatically capture approvals, rejected options, or later constraints. Another failure is letting each agent maintain a private summary. Private summaries diverge, and reviewers cannot tell which version guided a result.
A third failure is collecting context without an acceptance standard. If a task says “build the dashboard” but does not name the user action, scope boundary, and proof required, different agents can all produce plausible but incompatible work. Shared context becomes valuable only when it changes the decision an agent can make and the evidence a reviewer can expect.
Frequently asked questions
What is shared project context for AI agents?
Shared project context is the current, approved record of an app’s outcome, scope, decisions, source material and dependencies, plus acceptance evidence. It gives each AI agent the same basis for its task while showing which details are confirmed or open, with superseded as another option.
Should every AI agent receive the full project context?
No. Each agent should receive the context that governs its task, along with links to the decisions and dependencies that affect it. The full shared record remains available so an agent or reviewer can trace a requirement when a task crosses another workstream.
How do you prevent AI agents from using outdated requirements?
Version the decision record and mark the work affected by a change. When a requirement is updated, record the new approved choice, identify dependent tasks and acceptance checks, and reopen or review work that used the earlier decision.
More from thinQit
Use these pages to make the next step concrete.