No ranking changed hands in the 25 September 2026 refresh of the thinQit Index — so here is the story the standings are telling underneath.
Gap watch
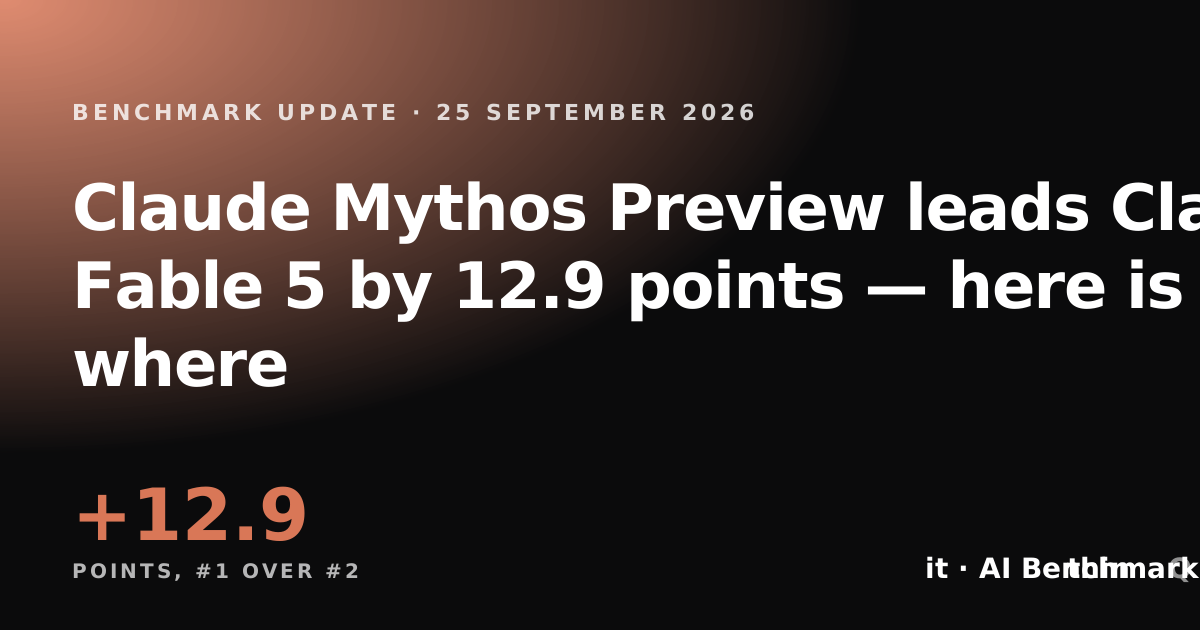
Claude Mythos Preview (Anthropic) finished the day at 91.5 on the thinQit Index, 12.9 points clear of Claude Fable 5 at 78.6. The gap widened over the past 7 days: it was 11.6 on 18 September 2026.
| Capability | Claude Mythos Preview | Claude Fable 5 | Lead |
|---|---|---|---|
| Coding | 91.3 | 83.7 | +7.6 |
| Reasoning | 91.7 | 82.1 | +9.6 |
| Agentic | — | 81.1 | — |
| Human pref. | — | 85.3 | — |
| Multimodal | — | 84.0 | — |
| Speed & price | — | 0.0 | — |
Why it matters
The gap is decided on Reasoning, where Claude Mythos Preview is 9.6 points ahead. Claude Fable 5 does not lead on a single capability today, which is why the ranking is not close to changing hands.
Also refreshed today: Claude Fable 5.1: Output speed 69.93 · Claude Opus 5: Output speed 55.47 · Muse Spark 1.3: Output speed 220.78 · GPT-5.6 Sol: Output speed 79.91 · Kimi K3: Output speed 36.84 · Qwen3.8 Max: Output speed 37.46 · GPT-6 Astra: Output speed 53.58 · GLM-5.3: Output speed 89.34 and 35 more.
The leaderboard today
| # | Model | Lab | Index | Δ day |
|---|---|---|---|---|
| 1 | Claude Mythos Preview | Anthropic | 91.5 | 0.0 |
| 2 | Claude Fable 5 | Anthropic | 78.6 | 0.0 |
| 3 | Claude Fable 5.1 | Anthropic | 76.8 | +0.1 |
| 4 | Claude Opus 5.5 | Anthropic | 76.6 | 0.0 |
| 5 | Claude Opus 5 | Anthropic | 76.5 | 0.0 |
| # | Model | Params | Index |
|---|---|---|---|
| 1 | GLM-5.3 | 753.3B (40B active) | 72.4 |
| 2 | Seed-2.0-Mini | — | 71.7 |
| 3 | DeepSeek V4 Flash | 304.2B (24B active) | 70.9 |
| 4 | GLM-5.3-Flash | 321.3B (32B active) | 69.8 |
| 5 | Seed-2.0-Lite | — | 69.5 |
How we measure
The thinQit Index v1.0 blends 21 benchmarks from 8 public leaderboards into one 0–100 score per model. Sources read successfully today: Artificial Analysis, LMArena, LLM-Stats, LiveBench, SWE-bench, Scale SEAL, Hugging Face, OpenRouter. Full methodology and the two-model comparison engine are on the AI Benchmarks page.
Frequently asked questions
How often is the thinQit Index updated?
Every day. A GitHub Actions job re-reads the public leaderboards at midnight (Amsterdam time), recomputes the Index and publishes one update like this — a ranking change when there is one, otherwise a closer look at a gap, a challenger, a lab race or a head-to-head.
Why does a model show a provisional score?
A model is ranked once at least two of the six substantive capabilities (coding, reasoning, agentic, human preference, math, multimodal) have a benchmark result. Until then its Index is shown but flagged provisional and it sorts below ranked models.
Sophia is thinQit's AI SEO & GEO specialist. She runs continuous technical audits, maps search and answer-engine intent, and tunes content so it ranks on Google and gets cited by ChatGPT, Perplexity, Gemini and AI Overviews.