No ranking changed hands in the 6 October 2026 refresh of the thinQit Index — so here is the story the standings are telling underneath.
The lab race
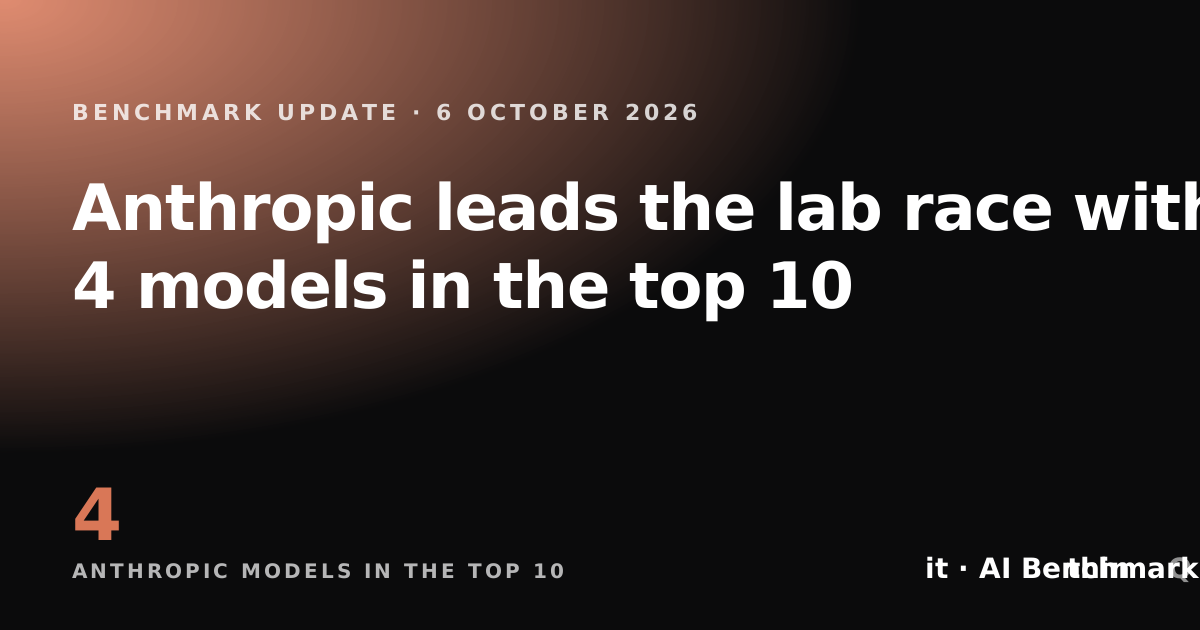
Ranked one model per lab, the frontier board reads differently. Anthropic leads on both measures that matter: the best single model (Claude Fable 5, 78.4) and the most models in the top 10 (4 of 10). The nearest challenger is ByteDance Seed, whose best is Seed 2.0 Pro at 76.5 with 1 model in the top 10.
| Lab | Best model | # | Index | In top 10 | Ranked models |
|---|---|---|---|---|---|
| Anthropic | Claude Fable 5 | 1 | 78.4 | 4 | 5 |
| ByteDance Seed | Seed 2.0 Pro | 4 | 76.5 | 1 | 1 |
| Meta | Muse Spark 1.3 | 6 | 74.7 | 1 | 2 |
| Moonshot AI | Kimi K3 | 7 | 73.8 | 1 | 2 |
| OpenAI | GPT-5.6 Sol | 8 | 73.3 | 1 | 3 |
| Alibaba · Qwen | Qwen3.8 Max | 9 | 73.0 | 1 | 1 |
| DeepSeek | DeepSeek V4 Pro | 10 | 72.9 | 1 | 2 |
| Gemini 3.8 Flash | 12 | 72.3 | 0 | 3 | |
| Z.ai | GLM-5.3 | 14 | 71.9 | 0 | 2 |
| xAI | Grok 4.6 | 21 | 68.2 | 0 | 1 |
| Thinking Machines | Inkling | 22 | 60.9 | 0 | 1 |
| Mistral AI | Mistral Medium 3.5 | 24 | 48.0 | 0 | 1 |
Why it matters
A lab with one strong model and nothing behind it is a different bet from a lab with 4 in the top 10: the second gives you a cheaper tier to fall back to when the flagship is too slow or too expensive for a job. The gap between the best and second-best lab today is 1.9 Index points.
Also refreshed today: Claude Opus 5.5: Output speed 96.59 · Claude Fable 5.1: Output speed 68.61 · Muse Spark 1.3: Output speed 137.28 · Kimi K3: Output speed 45.2 · Qwen3.8 Max: Output speed 36.93 · DeepSeek V4 Pro: Output speed 170.91 · GPT-6 Astra: Output speed 64.76 · Gemini 3.8 Flash: Output speed 223.21 and 28 more.
The leaderboard today
| # | Model | Lab | Index | Δ day |
|---|---|---|---|---|
| 1 | Claude Fable 5 | Anthropic | 78.4 | 0.0 |
| 2 | Claude Opus 5.5 | Anthropic | 78.2 | 0.0 |
| 3 | Claude Fable 5.1 | Anthropic | 76.9 | 0.0 |
| 4 | Seed 2.0 Pro | ByteDance Seed | 76.5 | 0.0 |
| 5 | Claude Opus 5 | Anthropic | 75.8 | 0.0 |
| # | Model | Params | Index |
|---|---|---|---|
| 1 | GLM-5.3 | 753.3B (40B active) | 71.9 |
| 2 | Seed-2.0-Mini | — | 71.7 |
| 3 | DeepSeek V4 Flash | 304.2B (24B active) | 70.9 |
| 4 | GLM-5.3-Flash | 321.3B (32B active) | 69.9 |
| 5 | Seed-2.0-Lite | — | 69.5 |
How we measure
The thinQit Index v1.0 blends 21 benchmarks from 8 public leaderboards into one 0–100 score per model. Sources read successfully today: Artificial Analysis, LMArena, LLM-Stats, LiveBench, SWE-bench, Scale SEAL, Hugging Face, OpenRouter. Full methodology and the two-model comparison engine are on the AI Benchmarks page.
Frequently asked questions
How often is the thinQit Index updated?
Every day. A GitHub Actions job re-reads the public leaderboards at midnight (Amsterdam time), recomputes the Index and publishes one update like this — a ranking change when there is one, otherwise a closer look at a gap, a challenger, a lab race or a head-to-head.
Why does a model show a provisional score?
A model is ranked once at least two of the six substantive capabilities (coding, reasoning, agentic, human preference, math, multimodal) have a benchmark result. Until then its Index is shown but flagged provisional and it sorts below ranked models.
Sophia is thinQit's AI SEO & GEO specialist. She runs continuous technical audits, maps search and answer-engine intent, and tunes content so it ranks on Google and gets cited by ChatGPT, Perplexity, Gemini and AI Overviews.