No ranking changed hands in the 26 October 2026 refresh of the thinQit Index — so here is the story the standings are telling underneath.
Frontier watch
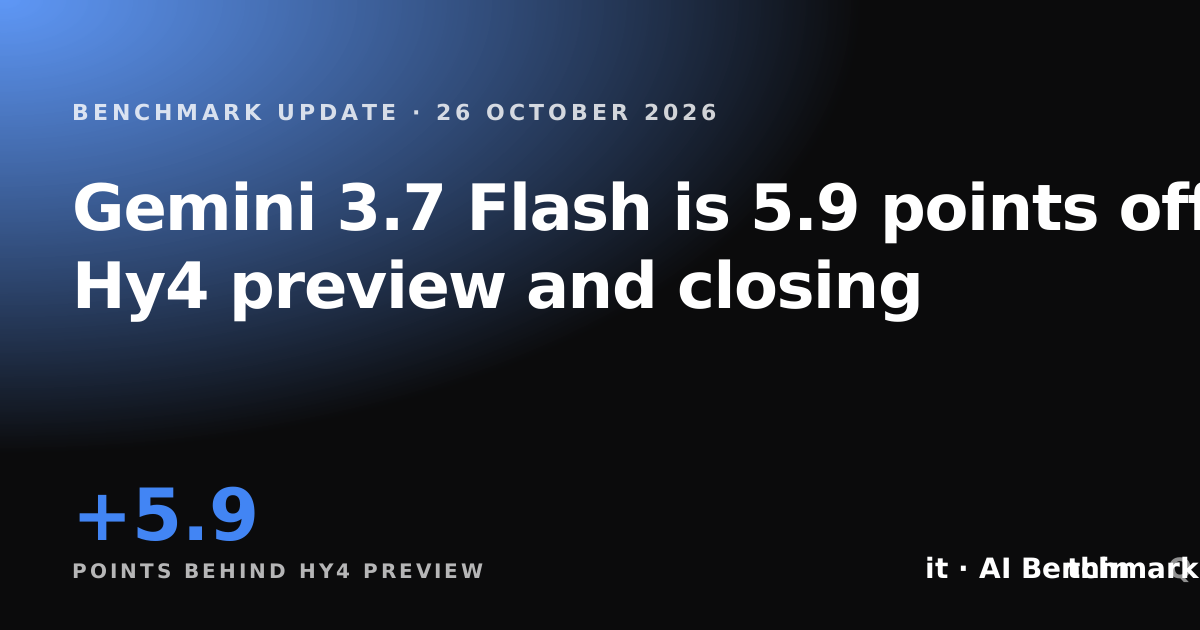
Nothing changed hands on the frontier board today, so the question is who is moving underneath it. Claude Opus 5.5 (Anthropic) holds #1 at 80.4 with Hy4 preview 1.6 points behind. The best-placed challenger from another lab is Gemini 3.7 Flash (Google) at #11, 5.9 points off #2 and 7.5 off the top.
| # | Model | Lab | Index | Δ 7d | Gap to Gemini 3.7 Flash |
|---|---|---|---|---|---|
| 1 | Claude Opus 5.5 | Anthropic | 80.4 | 0.0 | 7.5 |
| 2 | Hy4 preview | Tencent | 78.8 | −0.1 | 5.9 |
| 11 | Gemini 3.7 Flash | 72.9 | +1.5 | — |
Why it matters
At the rate of the last 7 days — Gemini 3.7 Flash +1.5, Hy4 preview −0.1 — the gap closes in about 26 days.
Where the gap actually sits: Hy4 preview leads Gemini 3.7 Flash by 14.6 points on Reasoning, while Gemini 3.7 Flash is already ahead on Speed & price.
Also refreshed today: Claude Opus 5.5: Output speed 94.76 · Hy4 preview: Blended price 1.25 · Claude Fable 5.1: Output speed 67.95 · GPT-6 Astra: Output speed 66.76 · Kimi K3: Output speed 41.28 · Qwen3.8 Max: Output speed 39.93 · GPT-5.6 Terra: Output speed 132.4 · GLM-5.3: Output speed 85.84 and 30 more.
The leaderboard today
| # | Model | Lab | Index | Δ day |
|---|---|---|---|---|
| 1 | Claude Opus 5.5 | Anthropic | 80.4 | 0.0 |
| 2 | Hy4 preview | Tencent | 78.8 | −0.1 |
| 3 | Claude Fable 5.1 | Anthropic | 78.3 | −0.1 |
| 4 | Claude Fable 5 | Anthropic | 77.9 | 0.0 |
| 5 | Seed 2.0 Pro | ByteDance Seed | 76.5 | 0.0 |
| # | Model | Params | Index |
|---|---|---|---|
| 1 | Hy4 preview | 780B (40B active) | 78.8 |
| 2 | GLM-5.3 | 753.3B (40B active) | 72.4 |
| 3 | Seed-2.0-Mini | — | 71.7 |
| 4 | GLM-5.3-Flash | 321.3B (32B active) | 70.3 |
| 5 | DeepSeek V4 Flash | 304.2B (24B active) | 70.1 |
How we measure
The thinQit Index v1.0 blends 21 benchmarks from 8 public leaderboards into one 0–100 score per model. Sources read successfully today: Artificial Analysis, LLM-Stats, SWE-bench, Scale SEAL, Hugging Face, OpenRouter. Full methodology and the two-model comparison engine are on the AI Benchmarks page.
Frequently asked questions
How often is the thinQit Index updated?
Every day. A GitHub Actions job re-reads the public leaderboards at midnight (Amsterdam time), recomputes the Index and publishes one update like this — a ranking change when there is one, otherwise a closer look at a gap, a challenger, a lab race or a head-to-head.
Why does a model show a provisional score?
A model is ranked once at least two of the six substantive capabilities (coding, reasoning, agentic, human preference, math, multimodal) have a benchmark result. Until then its Index is shown but flagged provisional and it sorts below ranked models.
Sophia is thinQit's AI SEO & GEO specialist. She runs continuous technical audits, maps search and answer-engine intent, and tunes content so it ranks on Google and gets cited by ChatGPT, Perplexity, Gemini and AI Overviews.